
 “How’s my paper doing?” It’s such a simple question, and in today’s hyperconnected world it’s relatively easy to work out who’s reading and talking about your scientific publications. But are there conversations you might be overlooking?
Tag Archives: jeffrey perkel
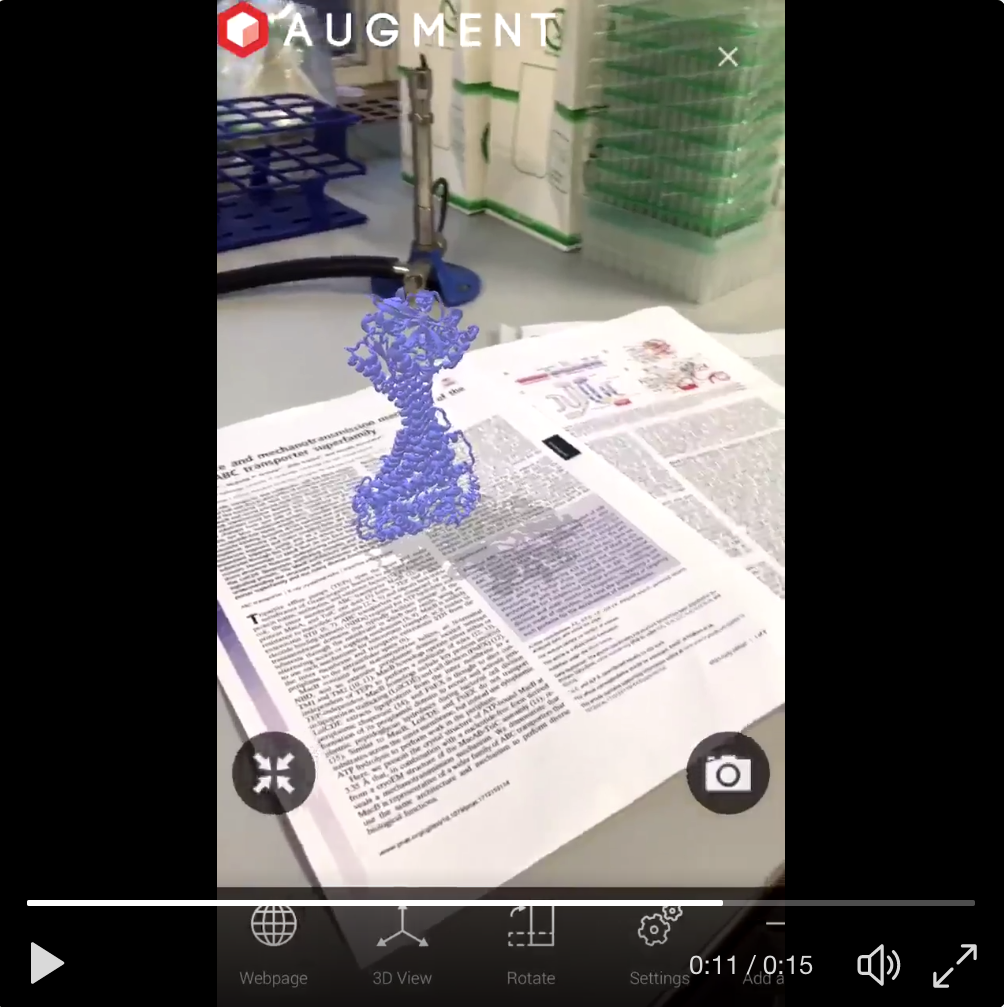
TechBlog: Augmented reality makes protein structures appear
{credit}Allister Crow/Twitter{/credit}
Update (9 Dec 2017): Allister Crow has updated his instructions to produce colored AR structures; they are available here.
Scientific publications represent years of work. It’d be nice if somebody read them.
That’s the problem Allister Crow faced as his postdoctoral work was published in early November.
Crow, a structural biologist at the University of Cambridge, UK, was part of a team, led by Vassilis Koronakis, that solved the structure of a bacterial protein called MacB, a pump protein that is involved in antibiotic resistance and toxin secretion. The paper went online November 6 in the Proceedings of the National Academy of Sciences. But how to get people — and especially those outside his immediate field — to notice?
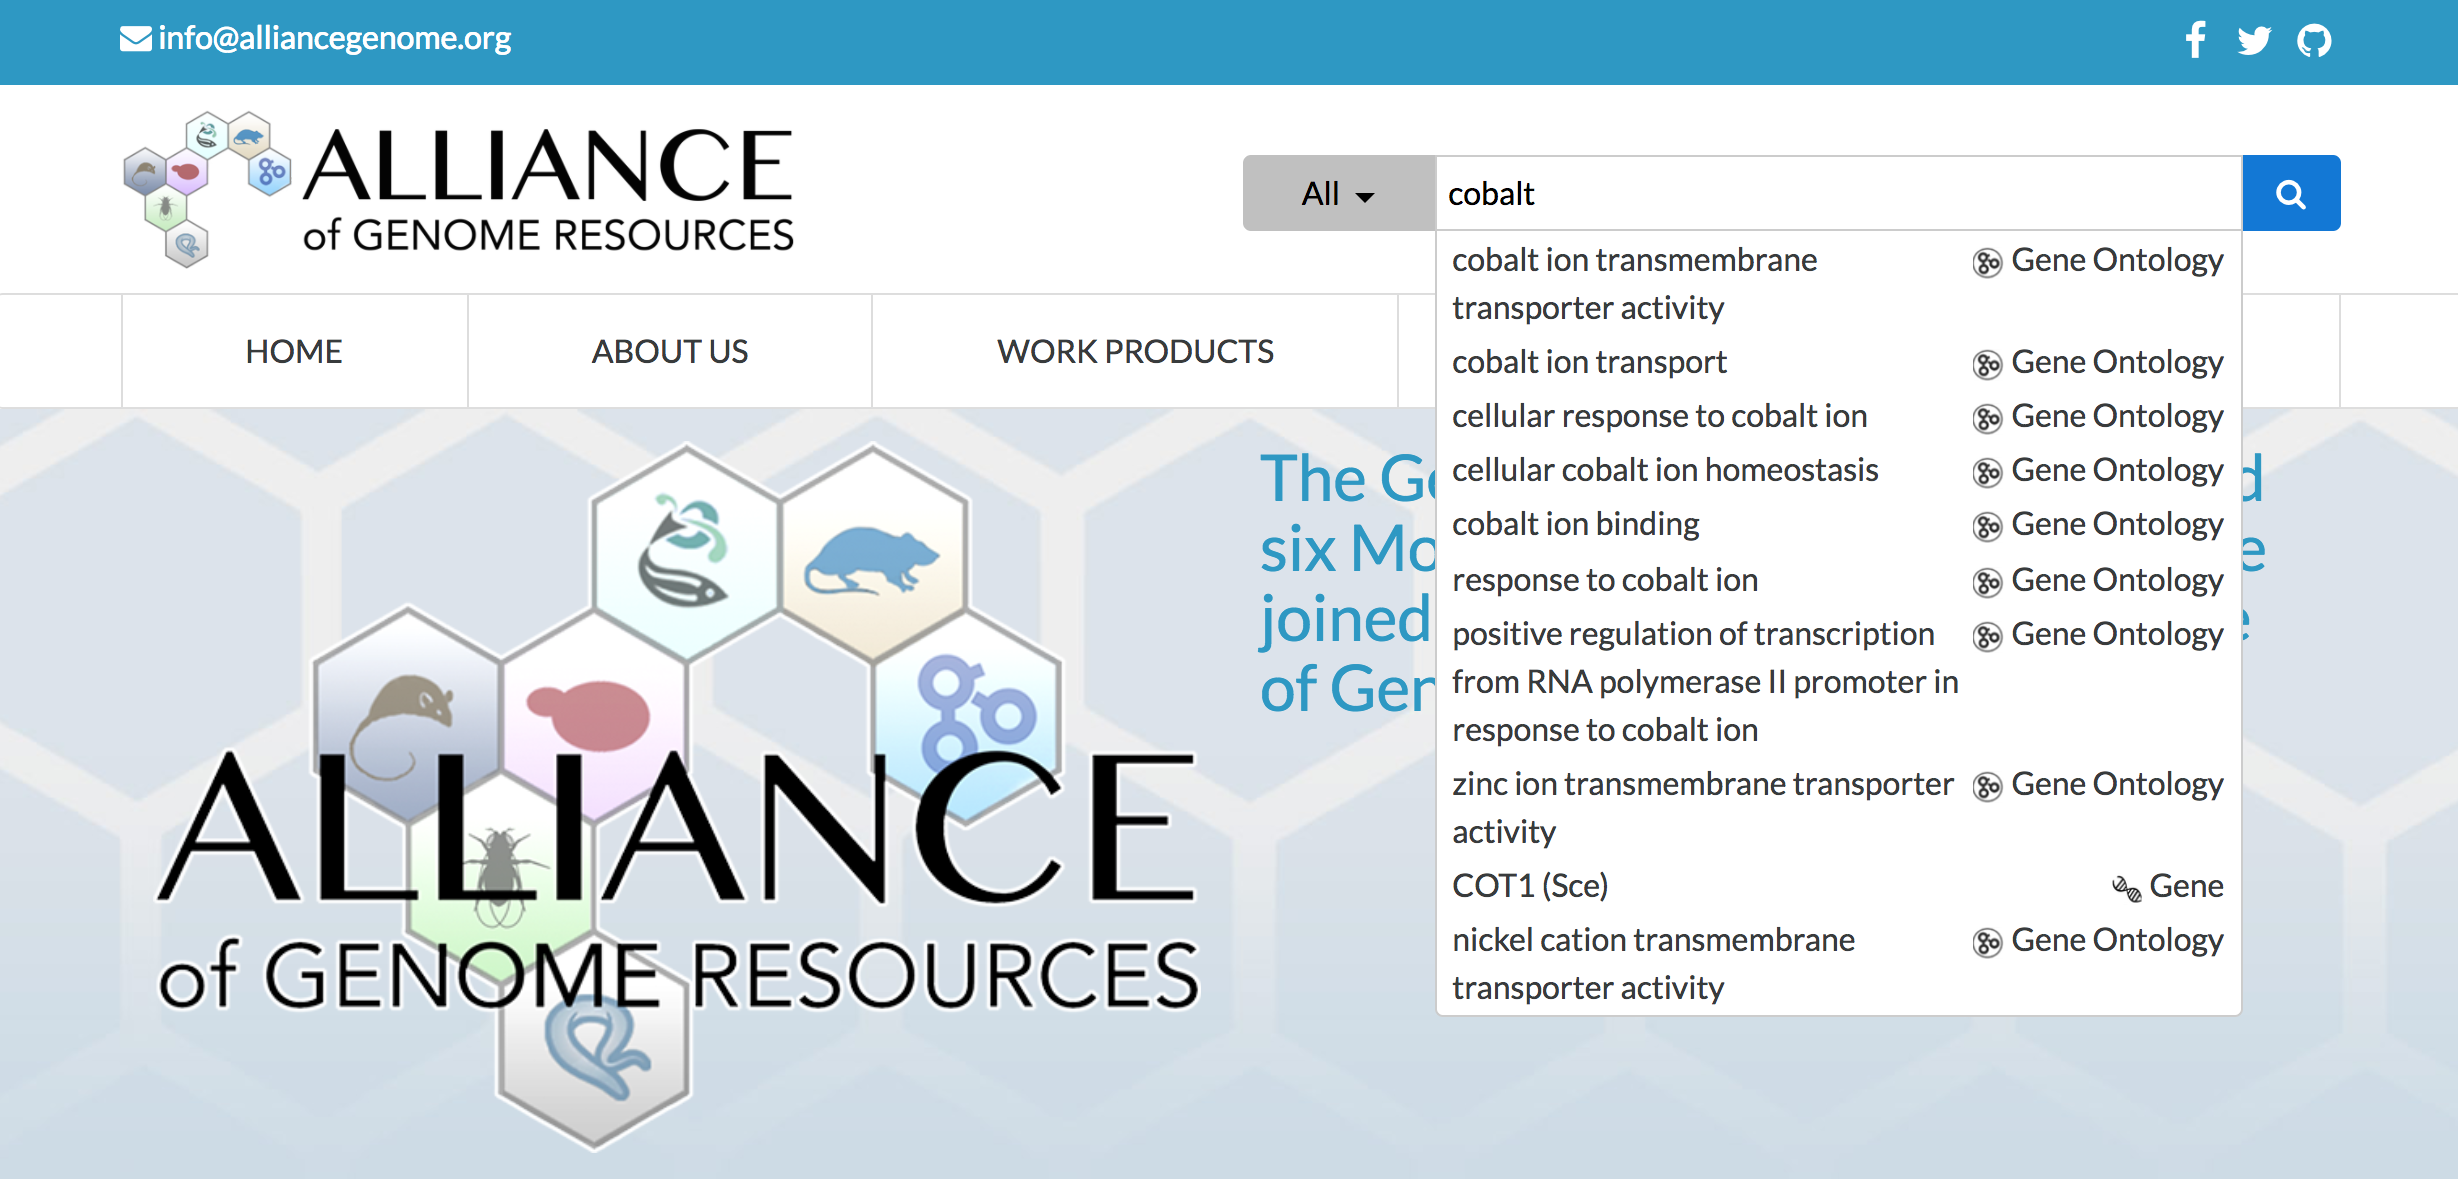
TechBlog: MODs get a unified search portal
{credit}Screenshot/Jeffrey Perkel{/credit}
For decades, the research communities surrounding the major model organisms have each had an online place to call home. There’s the SGD, MGD, and RGD — the Saccharomyces, mouse, and rat genome databases, respectively; FlyBase and WormBase for Drosophila and C. elegans; and ZFIN, the Zebrafish Information Network.
TechBlog: Timothée Poisot: Data science for the rest of us
{credit}Timothée Poisot{/credit}
Timothée Poisot recently travelled to London for MozFest 2017, “The world’s leading festival for the open Internet movement.” There, the quantitative and computational ecologist at the University of Montréal in Canada ran a session entitled “Scientific computing for the terabyte-less.” Here, he tells Naturejobs why life science research needn’t necessarily follow the Big Data model.
TechBlog: Bioconda promises to ease bioinformatics software installation woes
{credit}Johannes Köster/GitHub{/credit}
Bioinformatics is notoriously complicated, what with its arcane command-line interface, complex workflows, and massive datasets. For the uninitiated, simply installing the software can present a problem.
A new paper on the bioRxiv preprint archive describes one possible solution, a bioinformatics-focused package collection called Bioconda.
TechBlog: Interactive figures address data reproducibility
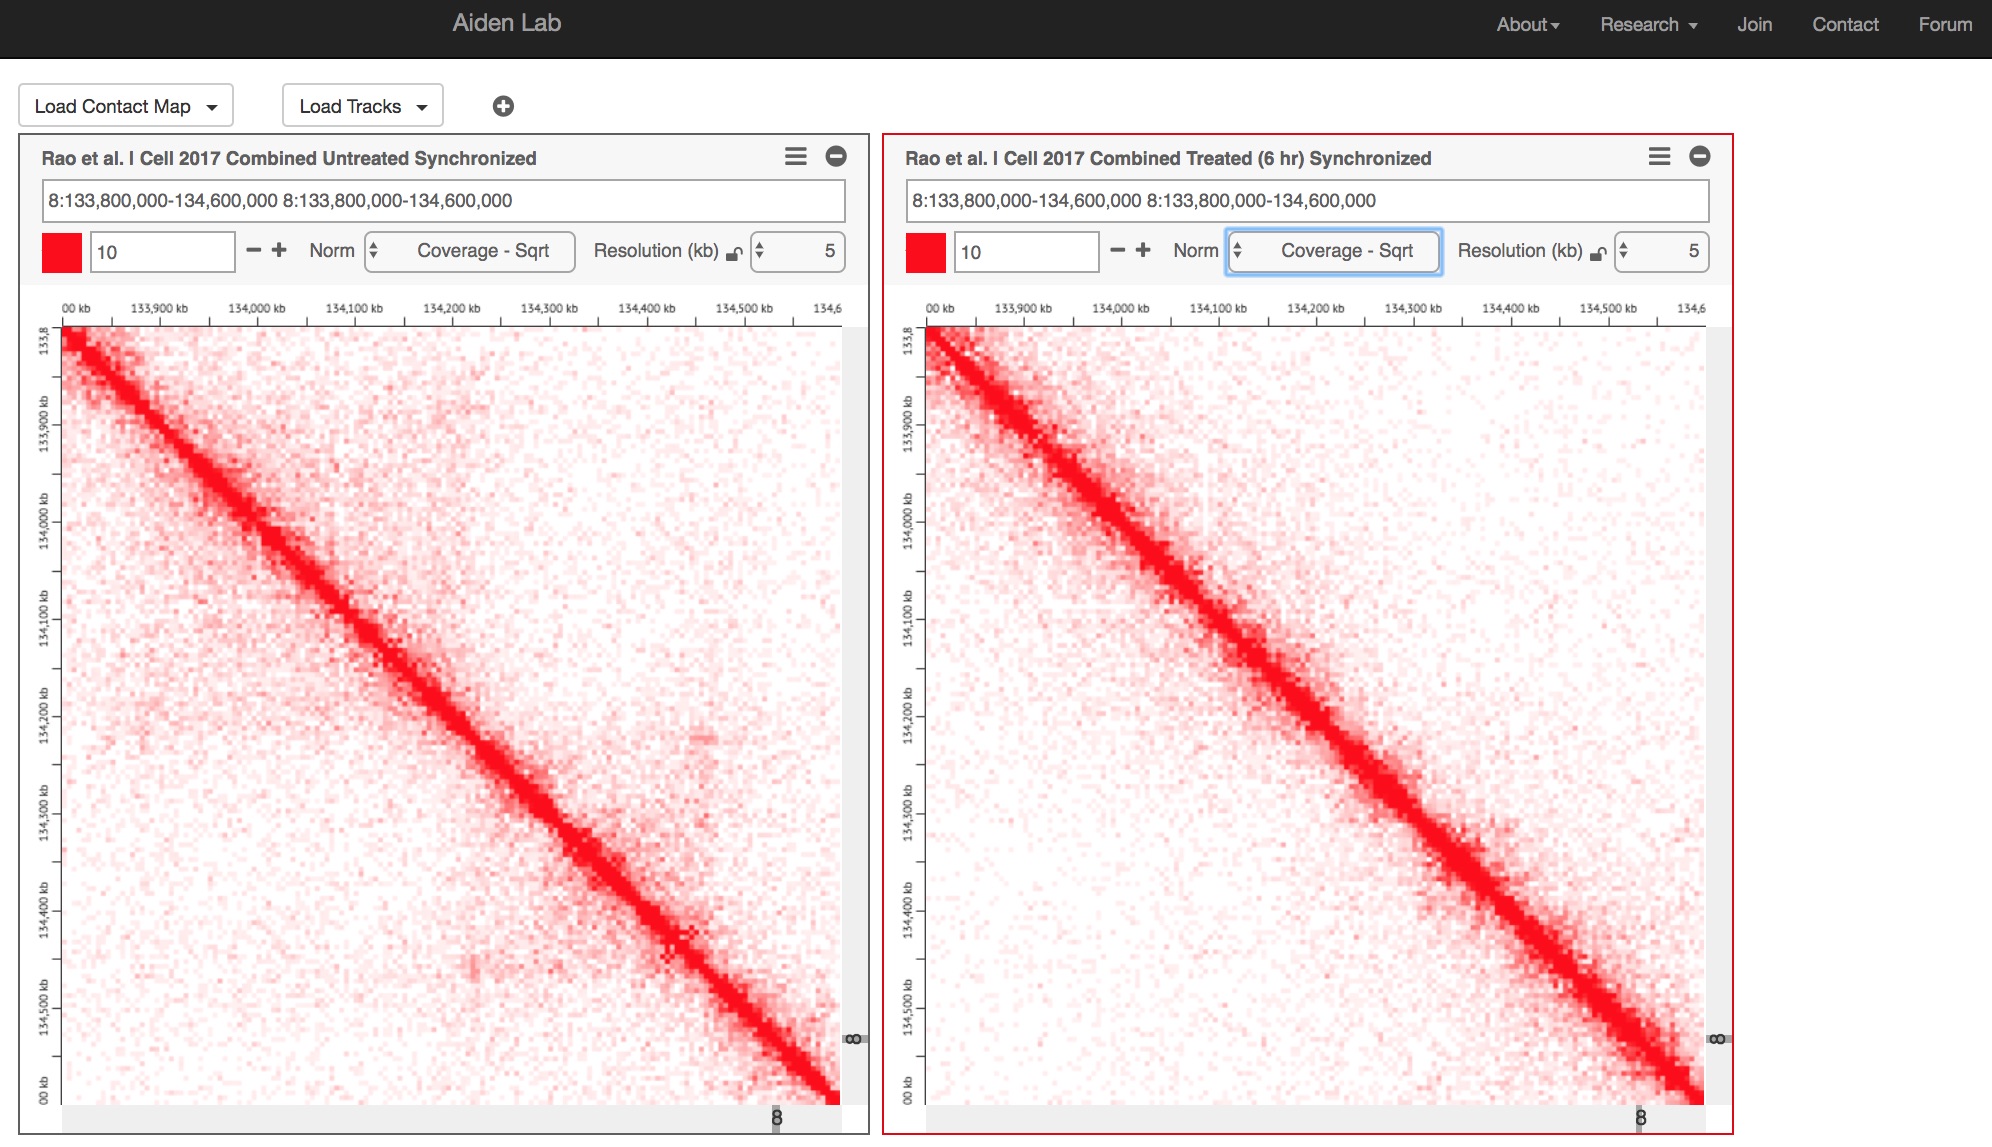
Juicebox.js{credit}Screenshot/Jeffrey Perkel{/credit}
Data reproducibility and transparency mean different things to different people, but one aspect involves allowing scientists to view and manipulate the data or code underlying published figures, both to double-check others’ work and to repeat those analyses using custom data. Over the past year, for instance, the open-access journal F1000Research has implemented integrations with Code Ocean and Plotly for viewing and manipulating programming code and figures, respectively. Now, a new publication showcases interactive figures for 3D genome analysis, too.
TechBlog: The nanopore toolbox
{credit}Nik Spencer/Nature{/credit}
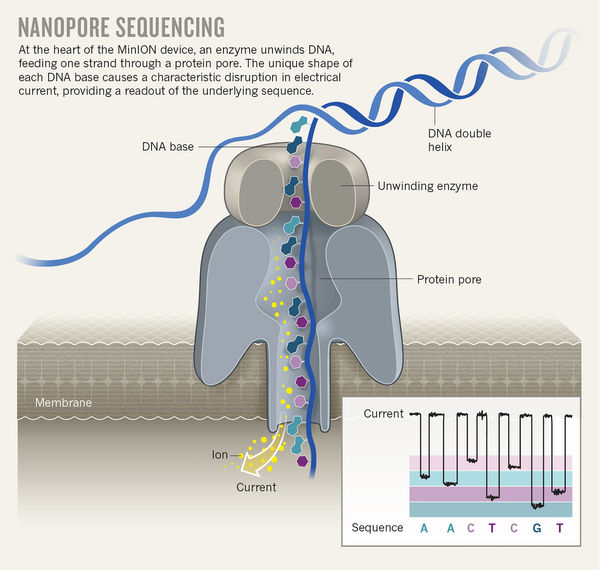
For this week’s Technology Feature, Michael Eisenstein wrote about the technology, applications, and challenges of nanopore DNA sequencing. In brief, the technology involves threading intact pieces of DNA through a tiny aperture in a membrane or other barrier, through which a current flows. As each base passes, it disrupts that current in a characteristic way, allowing specialized software to determine the sequence.
The technology has multiple benefits: it’s relatively inexpensive and compact, and produces exceptionally long reads. But the resulting error rate is also higher than some other technologies. What that means is, informatics tools designed to handle short-read data can often stumble when confronted with nanopore sequences. But a growing collection of dedicated long-read tools is rapidly filling in the gap. I asked a few nanopore veterans to help me compile a list.
TechBlog: Jupyter powers bioinformatics, again
Bioinformatics isn’t easy for newbies. It’s typically done on the Linux command line, where users direct the computer using text-based instructions rather than clicking a mouse.
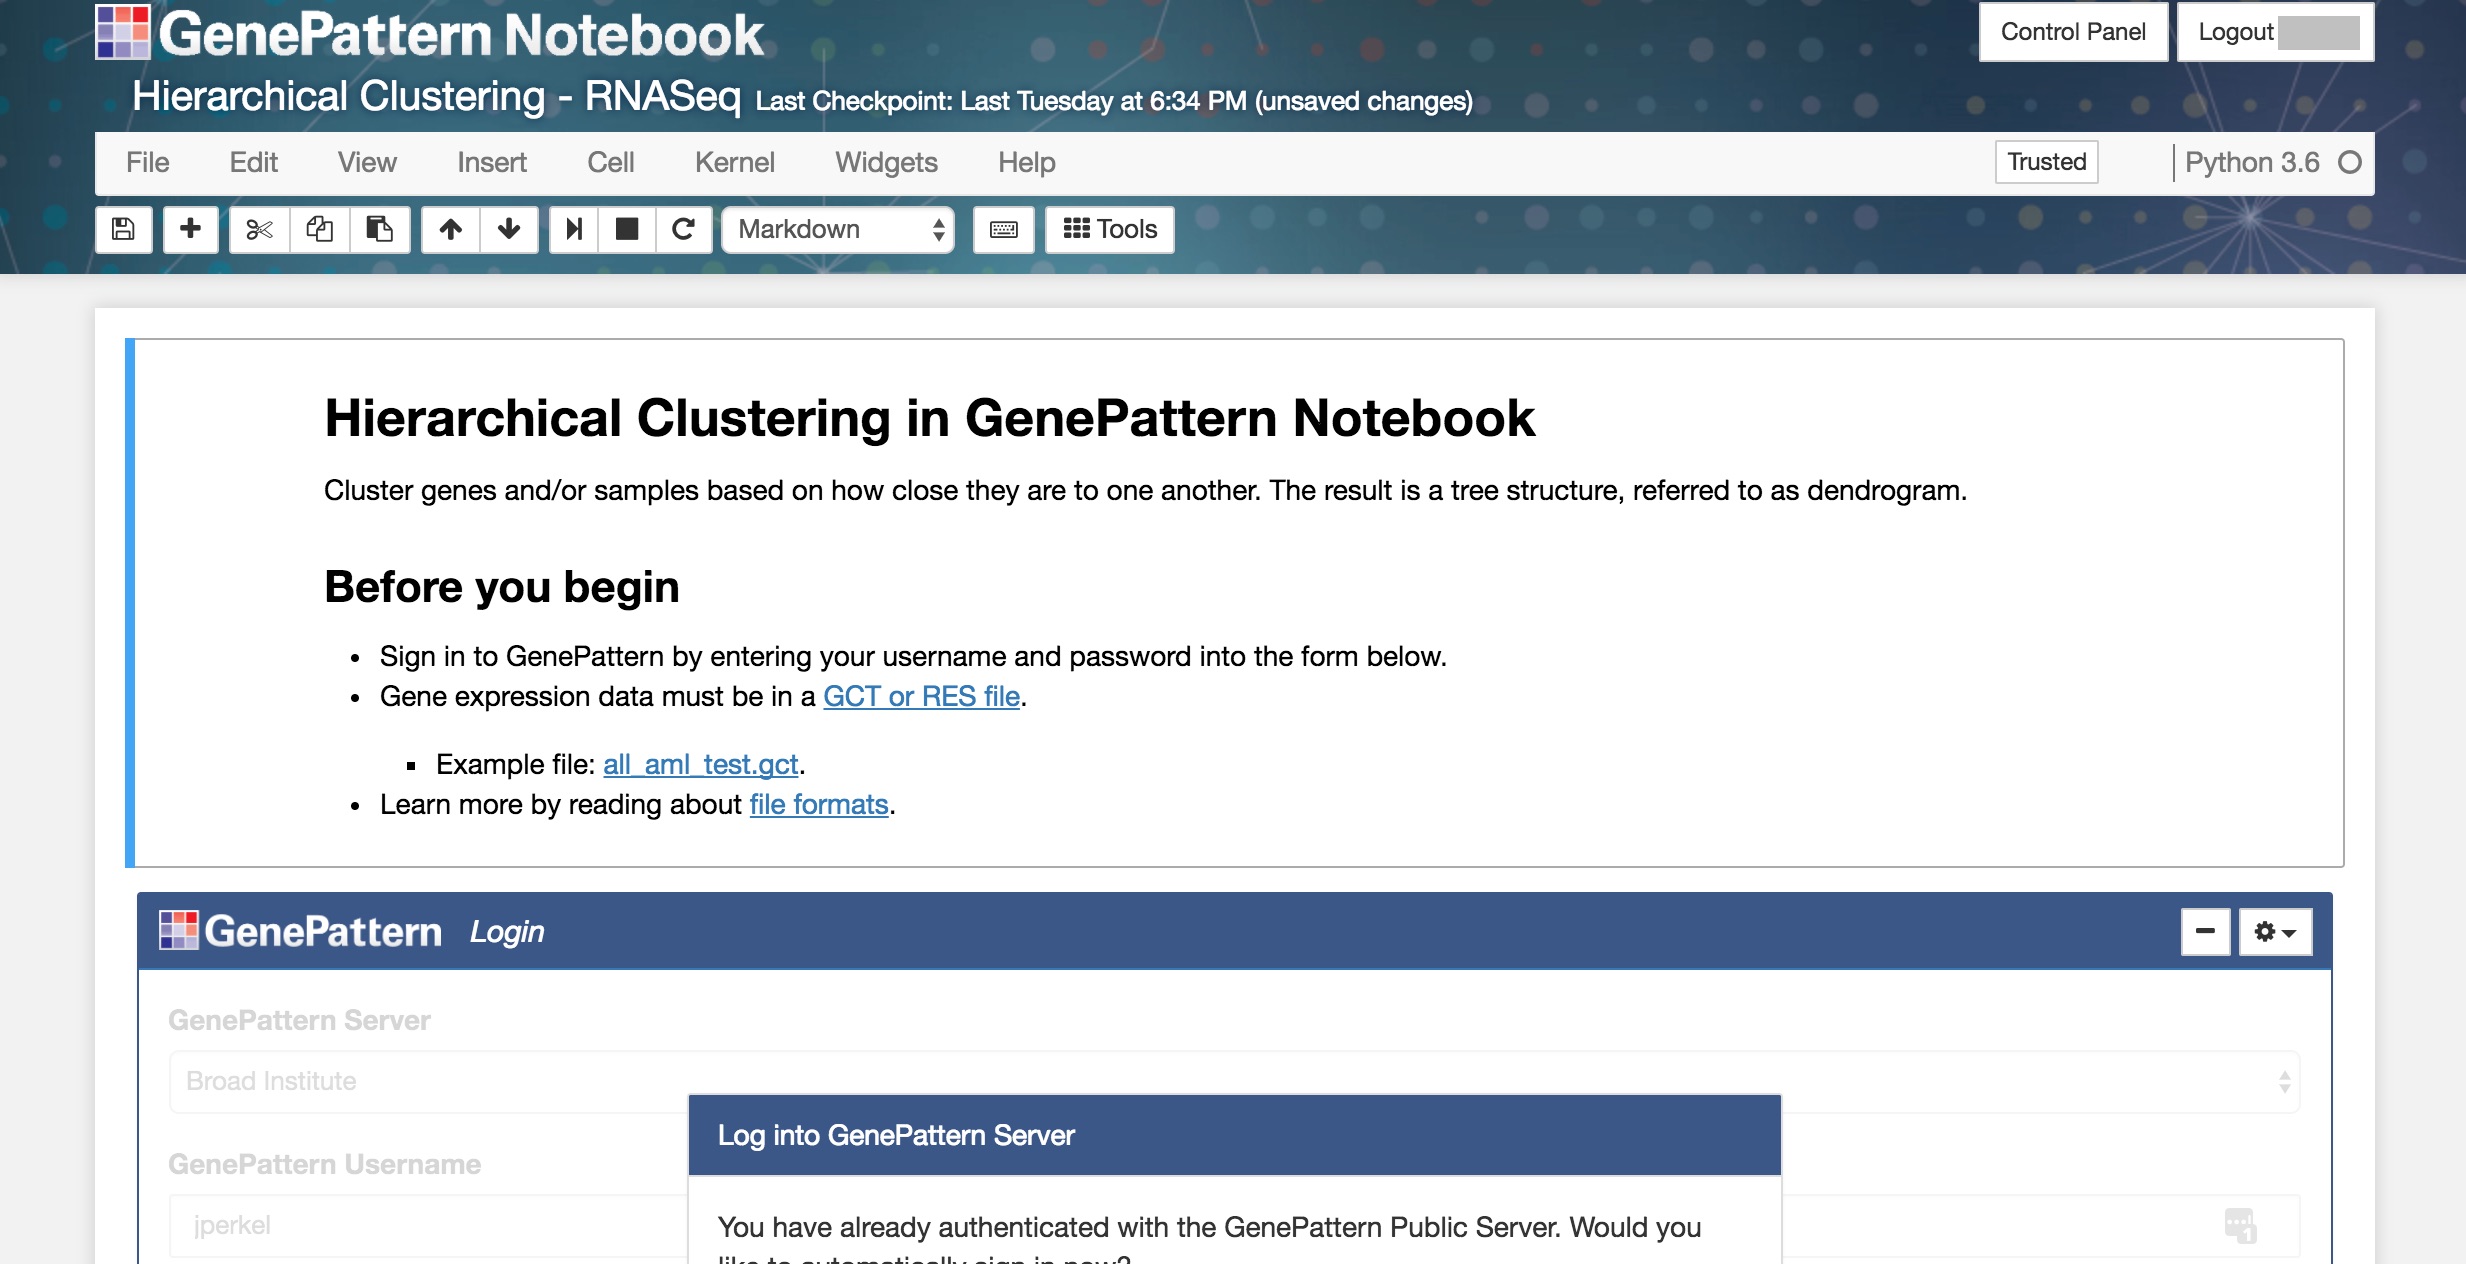
But there are alternatives. One popular choice is Galaxy; another is GenePattern. Both allow researchers to execute complex bioinformatics tools via open-source, point-and-click, web-based interfaces, freeing them from the burdens of the command line, programming, and software installation. As such, they make bioinformatics workflows relatively user-friendly. And that trend is continuing.
TechBlog: HiPiler simplifies chromatin structure analysis
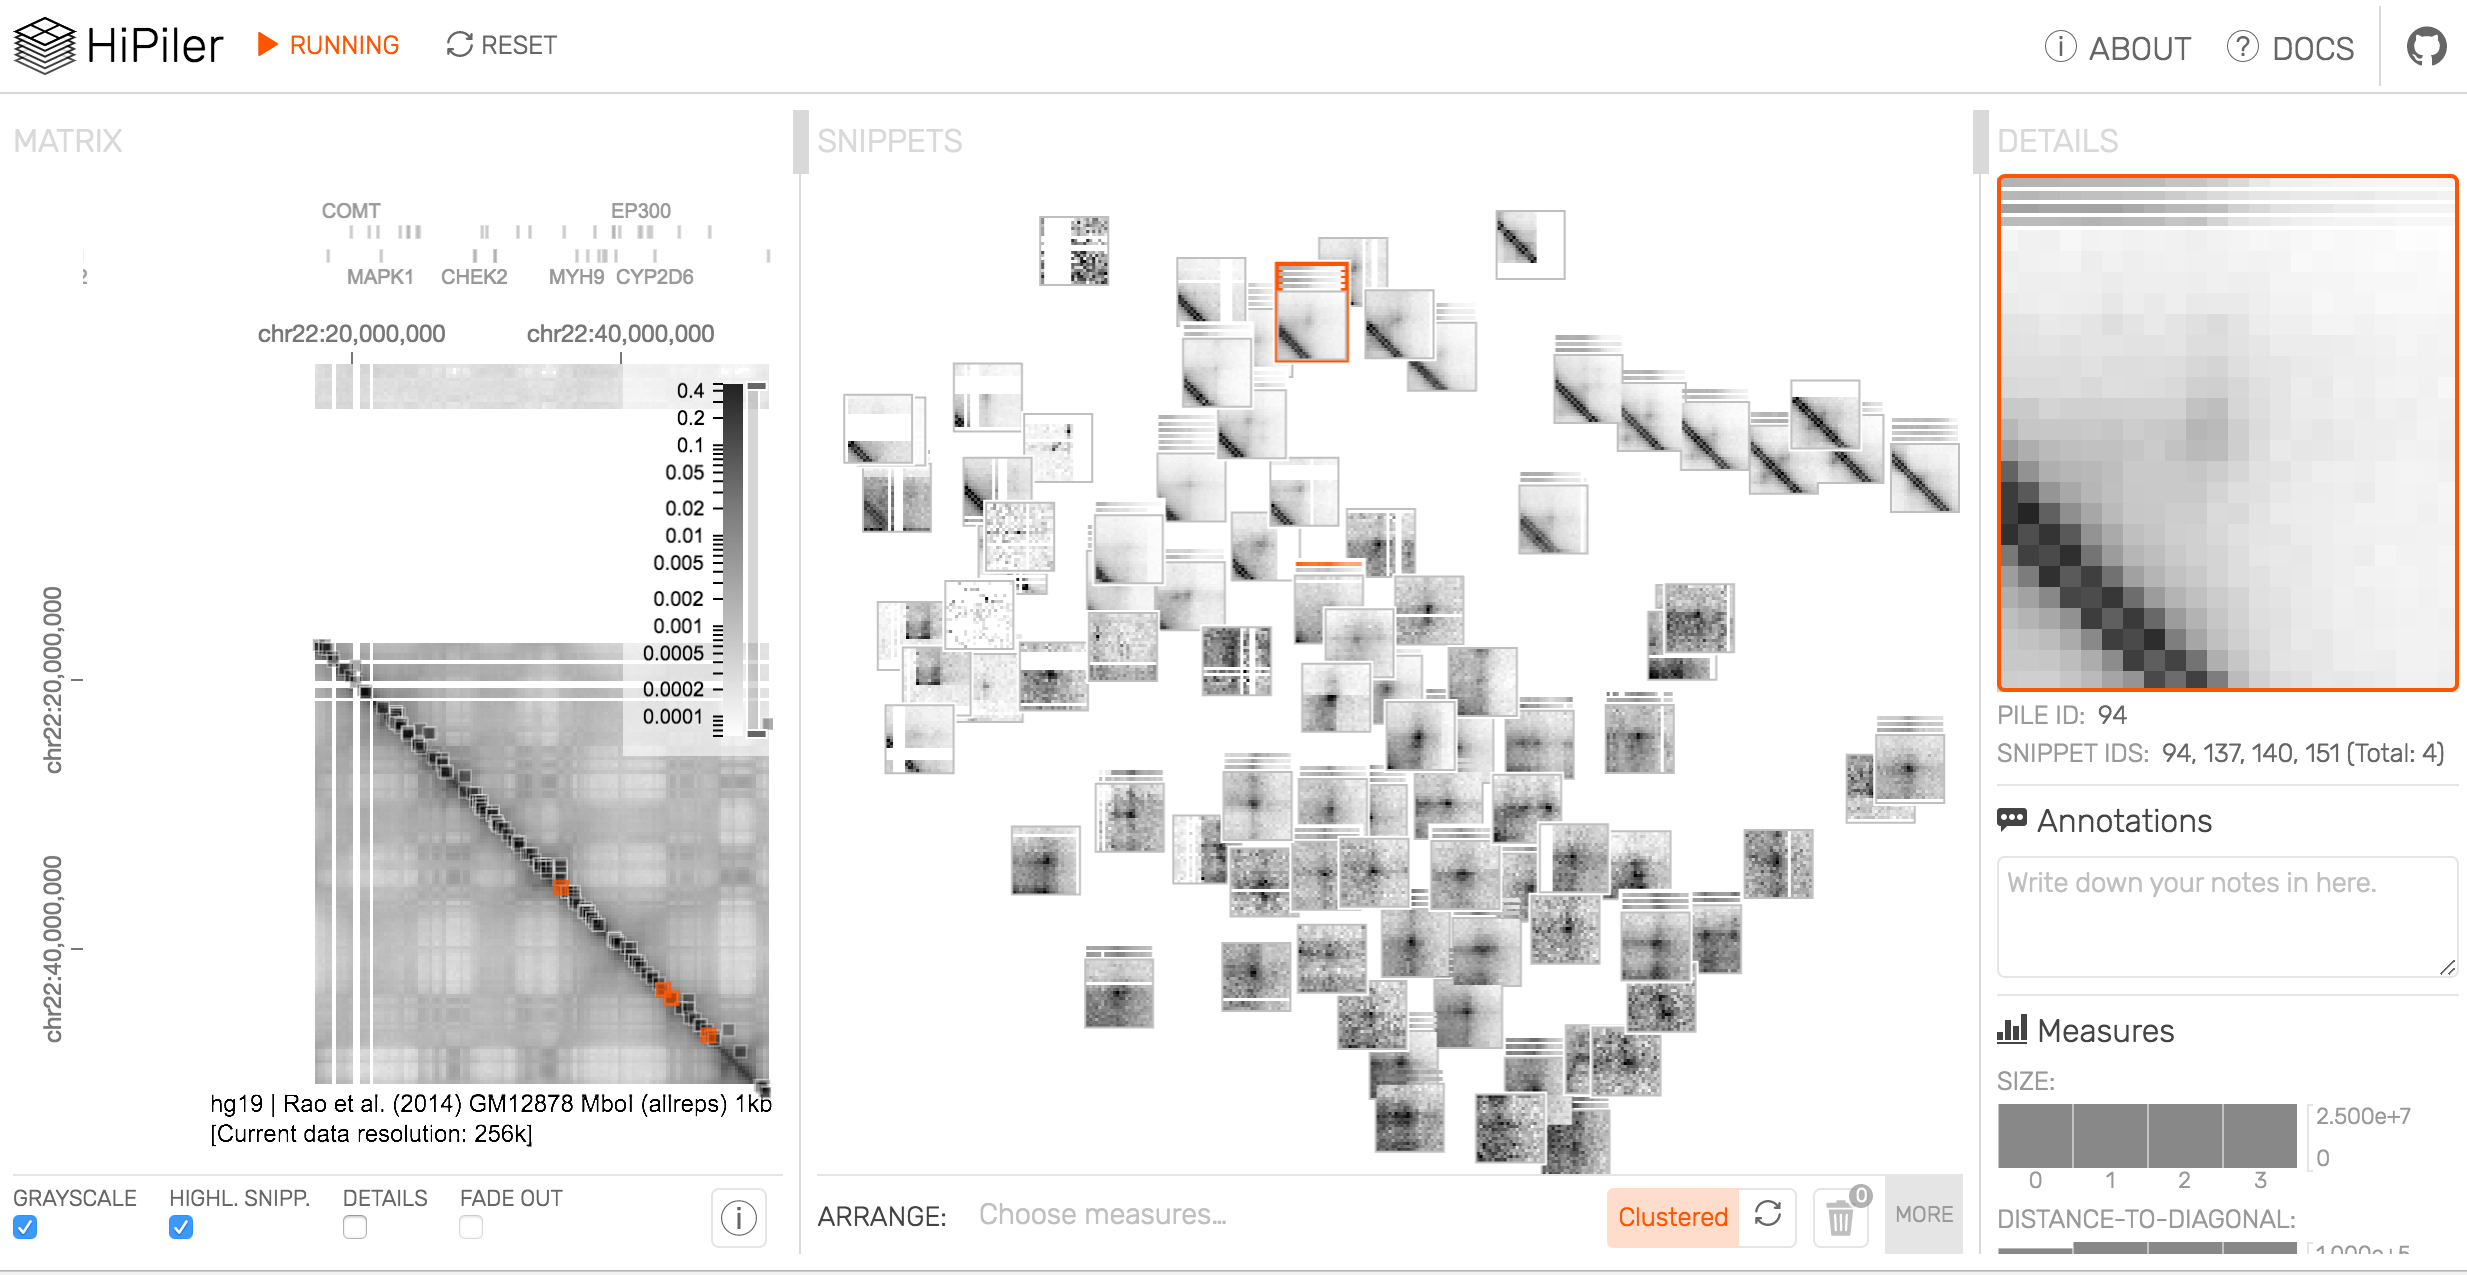
For my recent Toolbox on 3D genome visualization tools, Nils Gehlenborg at Harvard Medical School clued me into two interesting pieces of software. One, HiGlass, was included in my article; a related tool, HiPiler, was not. But that doesn’t mean it’s not worth talking about.
TechBlog: Mike Goodstadt: A circuitous route to bioinformatics
{credit}CNAG-CRG{/credit}
Most coders come to bioinformatics by one of two routes. They’re either biologists skilled in programming, or programmers with an interest in biology. Mike Goodstadt, the programmer behind the genome-visualization tool TADkit, took a different approach.
In the early-to-mid 1990s, Goodstadt was a student at the University of Bath in the UK. His course of study: Architecture. Continue reading