Scientific Data calls for submissions

Do you want credit for making your data available and reusable?

If so, Scientific Data can help. It’s a new type of open access journal publishing a new type of content, the Data Descriptor, designed to provide detailed descriptions of datasets: focusing on how these have been produced, by whom, and how they could be reused. We aim to make your data more discoverable, interpretable and reusable. We are calling for submissions now and launching in May next year.SD_Benefit_150 Continue reading →

Scientific Data releases two sample Data Descriptors

We recently released two sample Data Descriptors to help prospective authors interested in submitting manuscripts to Scientific Data. These samples were created to help scientists understand our unique scope and formatting requirements, and to illustrate the value of detailed descriptions of valuable datasets. Over the coming weeks we will be releasing more detailed information for authors, including Data Descriptor templates, to help prepare scientists for our call for submissions at the end of September.

Sample 1: Proteomic profiles of human embryonic stem cells, induced-pluripotent stem cells and precursor fibroblasts, prepared by Javier Munoz and Albert J.R. Heck

Sample 2: Sequencing of genomes, transcriptomes and methylomes of wild Arabidopsis thaliana accessions, prepared Robert J. Schmitz, Matthew D. Schultz & Joseph R. Ecker

See this page to view the full sample articles and to download experimental metadata

Continue reading →

Scientific Data to complement and promote public data repositories

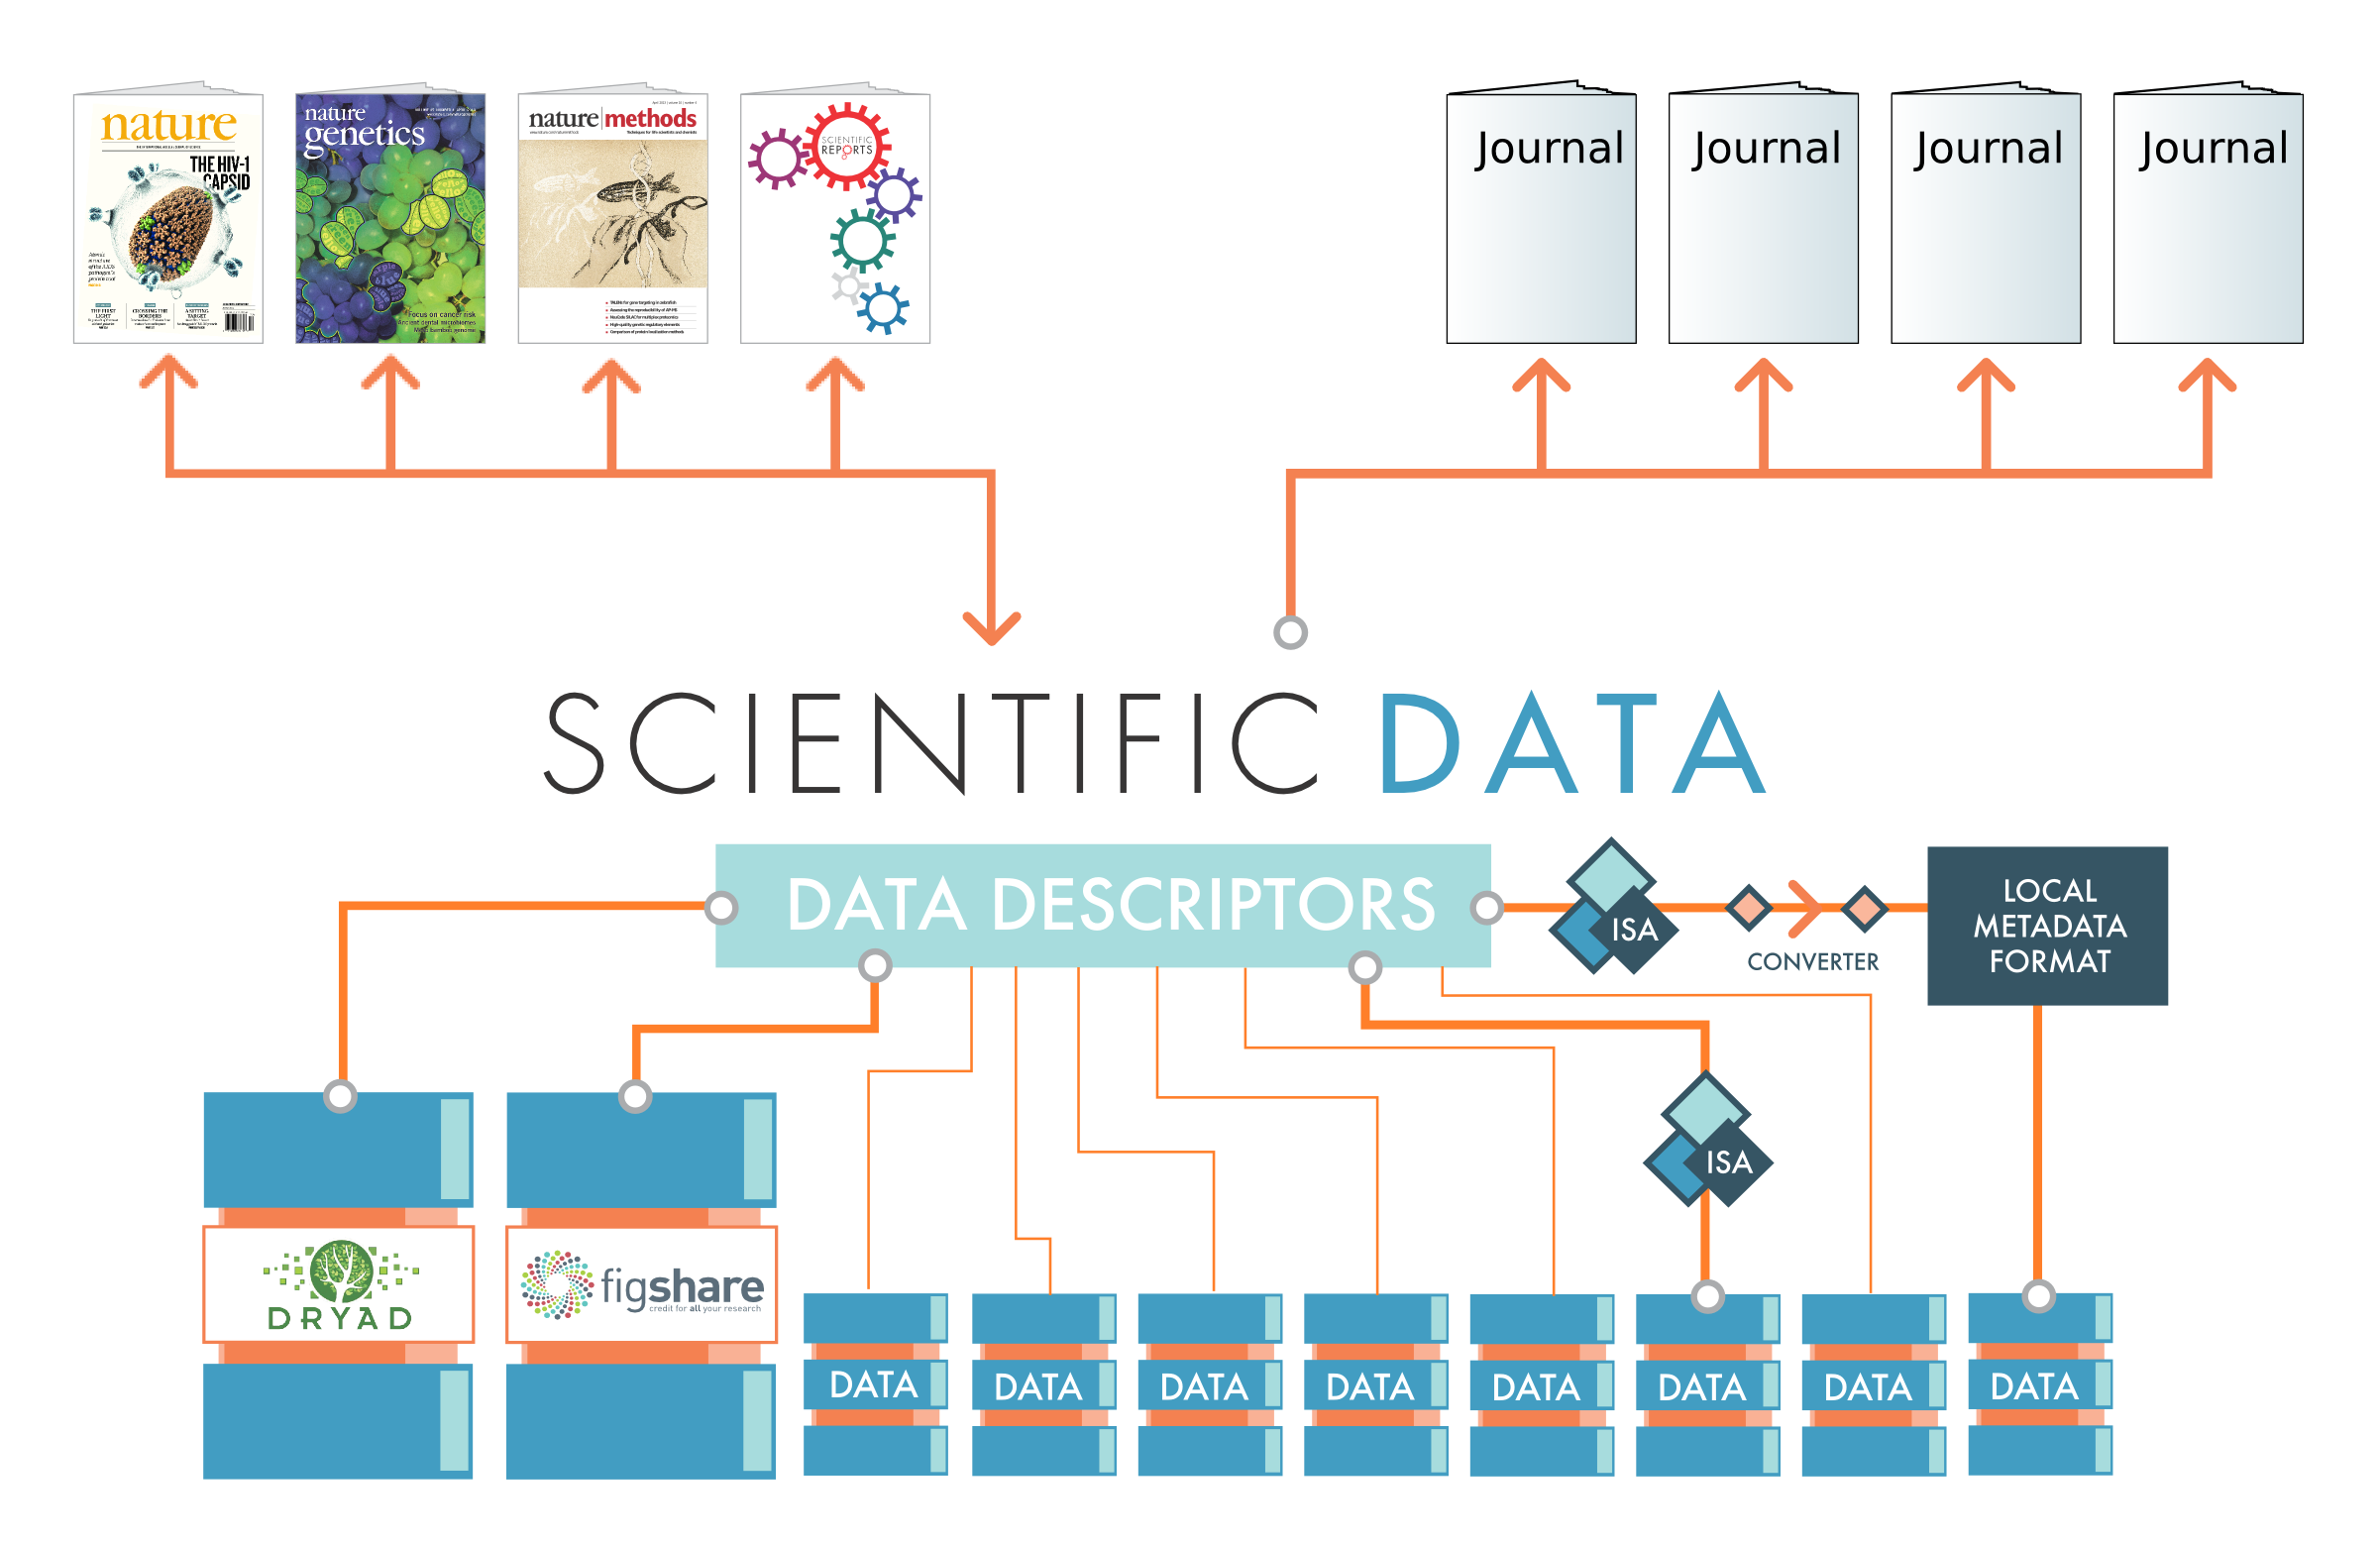
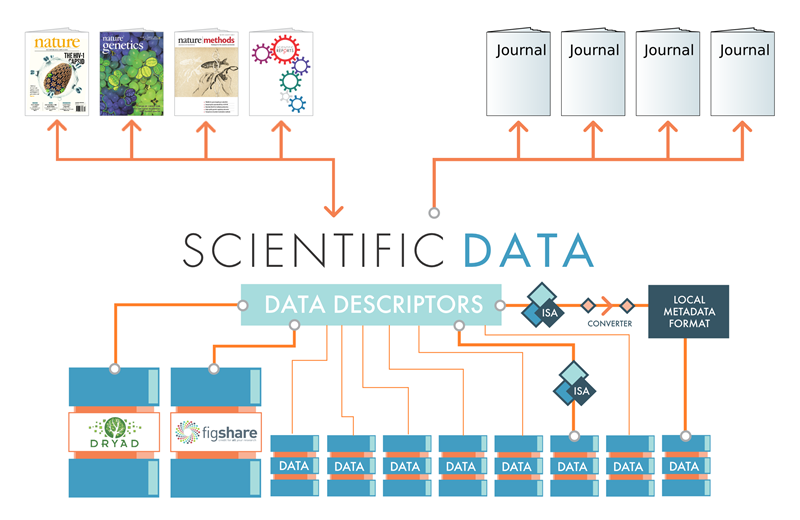
Scientific Data will be a forum for publications about datasets, but will not be a repository for primary datasets. Primary data associated with Data Descriptors will be stored in one or more external data repositories. Why this distinction?

This strategy helps us draw some clear lines around the goals of Scientific Data.  By ensuring that the primary datasets are stored in external systems, we make it crystal clear that our goal is to help authors publish content that promotes the scientific value and reusability of their datasets, not to control access to data. We feel that this is a progressive strategy that will help promote collaboration and data consolidation, rather than fragmentation.
repository_graphic

Publicly available scientific data is located in many different repositories, making it hard to find relevant datasets (aka the “data silo” problem). Scientific Data will provide a searchable publication platform where researchers can find high-quality datasets across many different data repositories. Data Descriptor publications will be linked to related research publications at Nature Publishing Group journals and external publishers, allowing scientists to navigate easily between research findings, rich data descriptions, and the actual data. We are working with two generalist repositories, Dryad and figshare, so that all datasets will have a home, and plan to develop metadata transfer pipelines with other repositories using the ISA framework.

Continue reading →

Research data hard to find? Watch our short video

You suspect that the data you need is out there, but how do you find it?  And if you find it, has it been described well enough for you to actually use it?

These frustrations are common to many scientists.  This week, we released a short 90 second video, humorously illustrating some of these obstacles, and introducing the aims of Scientific Data.

Watch it, share it, and help us get the word out about the importance of open, discoverable, and reusable research data!

Continue reading →

Eight questions introducing Scientific Data’s criteria for publication

Here at Scientific Data, we are busy developing guidelines for our future peer reviewers.  We believe strongly in the role that peer evaluation plays in the scientific process, and hope that Scientific Data will set a new standard for critical and constructive peer evaluation at a data-focused publication. Authors will be expected to convince referees that the data is worthy of wider use in the scientific community by supporting the technical rigor of the data collection procedures, the completeness of the data and its description, and alignment with existing community standards.  Referees will be asked to consider these points in detail, and will be free to request additional experiments when needed to support the data.

At the same time, referees will be asked not to base their evaluation on the perceived impact or novelty of the findings associated with the datasets, and authors will be asked to remove in-depth analyses or new scientific conclusions from submitted Data Descriptors. The peer review process will remain focused on data quality and reusability, not specific interpretations. Continue reading →

Our roadmap to engagement, your call

Are you a society, or a working group, a data center or library, a consortium or a grass-root organization that works to collect, curate, share and publish datasets from the research sciences? Are you developing or maintaining open, community standards that enable annotation, sharing and reuse of datasets? Do you have databases or tools, with an established user-base, that help with the data curation, reporting and sharing process? Do you work to harmonize, convert or bridge across different community-standards? If you are interested in learning when, where and how you can work with Scientific Data and become part of our community, then here is what you need to know. Continue reading →