A day in the life of a Scientific Reports manuscript assistant

William Coleman helps shed some light on the publishing business for Scientific Reports and Naturejobs.

Scientific Reports is a rapidly growing online open access journal that publishes research from all areas of the natural and clinical sciences. As one of over twenty manuscript assistants at the journal, one of my main tasks is to quality check author submissions in our online manuscript tracking system before they’re sent to our editorial board and, potentially, to peer review.

William pic

William Coleman

Continue reading →

The great outdoors

Summer is here in most parts of the world, and that means fieldwork for many junior (and senior) researchers. But journeying afar for days or weeks, though crucial for your research programme, can also mean a lot of prep work, hassle and unforeseen glitches.

{credit}Claire Asher{/credit}

How do you navigate these trips if you have children? What should you expect and prepare for if you’ll be living in close quarters with colleagues whom you may not know very well? How do you handle arduous endeavours like scaling mountains or climbing trees?

Continue reading →

So you want to be a data scientist (again)?

Put your natural science skills to work in a data science career

Guest contributor Daniel Harris of SoftwareAdvice.com

The explosive economic impact of big data has blurred the line between the business world and the scientific world like never before. A new type of business leader, the data scientist, has evolved as an amphibian, capable of thriving in both worlds, swimming in data lakes to bring useful insights back to the solid ground of business concerns.

Of course, companies have been using business intelligence (BI) tools to analyse their operational and financial performance metrics for decades.

But datasets generated by the web are so large that they must be stored on clusters of servers with thousands of nodes. Traditional methods for analysing these datasets have faltered, necessitating a more scientific approach.

Continue reading →

Enabling the effective sharing of clinical data

This blog was written by Mathias Astell & Iain Hrynaszkiewicz and was originally published on the DNAdigest blog.

The benefits of sharing data generated by researchers have long been understood to be of great value to science (as exemplified by this British Medical Journal piece from 1994). And over recent years there has been a rapid increase in the ability to share and access research data – as can be seen in the rise of data journals (such as Scientific Data and Gigascience), the increase in research data repositories (both general and subject-specific), and the establishment of data sharing policies around the world. Continue reading →

Data Reuse: An Interview with Daniele Marinazzo

Data Reuse Daniele Marianazzo

Daniele Marinazzo with data from Gorgolewski et al. paper {credit}Daniele Marinazzo{/credit}

Daniele Marinazzo is an associate professor at the University of Ghent in the department of Data Analysis of the Faculty of Psychology and Pedagogical Sciences.

He and his research group focus on methodological and computational aspects of neuroscience research. In particular developing, implementing and validating methods rooted in statistical physics for the study of brain connectivity and activity – investigating how information is stored and transferred in complex networks and how these results are then translated to the brain. Usually their validation of methodologies is done on publicly available data, and the code is always shared.

Daniele became aware of a dataset that could be of benefit to his research through the author of the data posting about it on Twitter. Daniele was then able to effectively utilise and implement this data into his research after the author of the original data published a Data Descriptor in Scientific Data. We caught up with Daniele to find out about his experiences of finding, sharing and using data. Continue reading →

Five top tips for getting your paper noticed

Your research breakthrough doesn’t just need to be read by the experts, says Mark Lorch.

Guest contributor Mark Lorch

You’ve just made the breakthrough you’ve been dreaming of. The days-weeks-months-years in the lab or field have all paid off, and everything has dropped into place. It’s the sort of moment that we scientists live for – the buzz of discovery. So now it’s time to publish.New Image

Tell your peers about your work and hope it leads to new and even greater things for you, your fellow scientists, and society. But is that really enough? Maybe there’s a wider audience for your science, outside of the narrow confines of your academic circle. Maybe it has applications in other fields, or perhaps the public would like to (or even should) know about it. Plus of course if you get your paper noticed it’s much more likely to have the citations and impact that you, your department and all the metric measurers have been hoping for.

In the open access era there’s nothing stopping anyone from downloading your paper. But there are still hurdles to overcome before getting the wide readership your paper deserves. Based on my experience, here’s five tips for helping your paper reach the widest possible audience. Continue reading →

#Scidata15: Make the most of your research: Publish better data

Primary research papers are the currency of academics, but they’re also part of a much wider body of knowledge that is restricted by a lack of transparency.

Guest contributor Lakshini Mendis
naturejobs-blog-Scidata15-ResearchData-for-Publications

{credit}Image credit: SCIENTIFIC DATA/LUDIC GROUP{/credit}

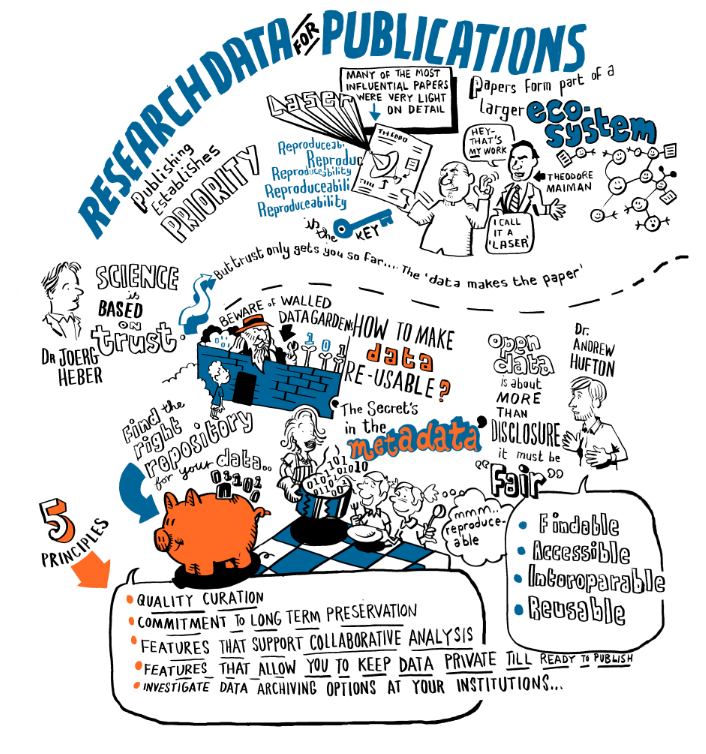
Historically, a great deal of trust has been placed in statements made in research papers for which the underlying data have not been shared. The invention of the laser was described in a paper containing just three data-points, for instance, and Watson and Crick first described the structure of DNA in a paper without any data at all. But with about 1,500 papers retracted since 2012, and 26.6% due to misconduct, scientific papers are now firmly under the microscope.

Improving the availability and readability of original research data would go a long way to improving matters. And as scientific publishers largely determine how research data is disseminated, their involvement will be central to any change. Speaking at Publishing Better Science Through Better Data in late October 2015, Dr Joerg Heber and Dr Andrew Hufton, editors at Nature Communications and Scientific Data respectively, emphasised that to make the most of research data it must be more open.

Overcoming the data-sharing challenge

According to Hufton, the status quo is for researchers to only share data with others directly. As well as being inefficient, data associated with published work disappears at a rate of about 17% a year as a result of researchers failing to properly catalogue findings. There is now, therefore, a move from scientific publishers to make data findable, accessible, interoperable and re-useable – or, to use an acronym as those of a scientific persuasion are so often inclined to do, FAIR. Continue reading →

#Scidata15: Big data: Challenges create opportunities

The era of big data brings with it a sea of opportunities for development and innovation.

Guest contributor Daniela Quaglia

naturejobs-blog-Scidata15-Opportunities-from-Research-Data

{credit}Image credit: SCIENTIFIC DATA/LUDIC GROUP{/credit}

Big data is here to stay. As scientists, we stand to benefit by being part of this exciting revolution. At the second Publishing Better Science through Better Data conference, held in London on October 23rd, Dr. Ewan Birney, joint associate director of the European Bioinformatics Institute (EBI), and Dr. Timo Hannay, founder of SchoolDash (a website that provides statistics about schools in England), walked us through some of the opportunities that arise from working with big data.

Opportunities in biology

Birney spoke about how the increase in big data is influencing the way we do biology. He promised to give the audience “an EBI centric view of the world”. I’m glad he did, because every scientist wanting to use big data should understand how EBI can help them.

EBI takes data provided by laboratories and stores, verifies, classifies and shares it. This approach means that a wealth of molecular-biology data, from DNA sequences to full systems (such us biomolecular pathways and metabolomics data), can be found in one place. As most scientists do not want to have to work from shared data in their raw form, the institute also works with the scientific community to convert original data into useful formats. Data from the Human Genome Project provides a compelling example of how such transformations can benefit the community — as Birney pointed out, not even the most experienced researchers want to analyse such complex raw data. Continue reading →

#SciData15: Get more out of your research data

Researchers shared their tools to help scientists use and share data more effectively at the 2015 Publishing Better Science Through Better Data conference.

Guest contributor Rehma Chandaria

naturejobs-blog-Scidata15-Lightning-Talks

{credit}Image credit: SCIENTIFIC DATA/LUDIC GROUP{/credit}

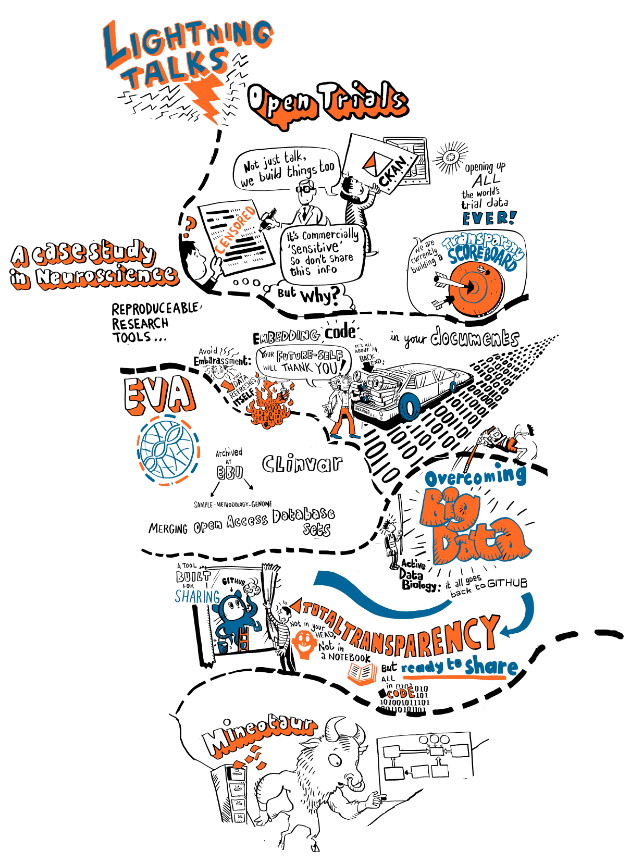
The session of lightning talks at the 2015 Publishing Better Science Through Better Data conference was strategically scheduled to combat the post-lunch lull that often occurs. Five speakers had seven minutes each to tell the audience about their tools for helping scientists to use and share data more effectively.

Dr Sam Payne and Dr Balint Antal have both written programmes that allow researchers to collaboratively analyze and visualize large amounts of data. Payne of the Pacific Northwest National Laboratory in Washington State developed Active Data Biology, a tool for interactively exploring and analyzing ‘big data’. He demonstrated how the programme can be used to assess proteomics data in the form of a heatmap — you can click on various proteins, conduct real-time analytics, save the proteins you find interesting and look at what your collaborators have saved. Rather than having the information hidden away in your notebooks or in your head, everything is stored on GitHub so it’s transparent and available to everyone involved. Mineotaur, developed by Antal of the University of Cambridge, UK, is based on a similar idea. It is an open-source tool designed for biologists to explore high-throughput microscopy data. Mineotaur can also be used to share research findings and allow others to analyse them further. It can even be embedded in publications to allow readers to explore the data for themselves. Continue reading →

Data sharing: Contribute to the community

Data sharing can make a significant contribution to the scientific community, but it comes with challenges, says Caroline Weight.

Guest contributor Caroline Weight

We have all heard of it. We are all worried about it. We hear whispers of it in the corridors. We are advised to be careful what we say to ‘others’. We constantly check the literature. It matters to us. After all, it is our careers on the line.

‘Scooped’.

The process of publication is vigorous, competitive and tricky. It’s not uncommon for five years to pass between writing the grant application and publishing the work. Big labs with state-of-the-art facilities stand a better chance of getting their work out there first, given the extra manpower and often more-established protocols. This race for ownership of the data makes it difficult to share information and present new findings at meetings or conferences. Even at manuscript submission, there is often a chance to actively inhibit particular referees in case of conflicts of interest or personal competitors, to retain the novel concepts and data until they have been made public. Not until the publication has been accepted and is in print can you heave a sigh of relief and move on to the next project. Yet, sharing of data is essential to the progression of science in the modern world. Continue reading →